

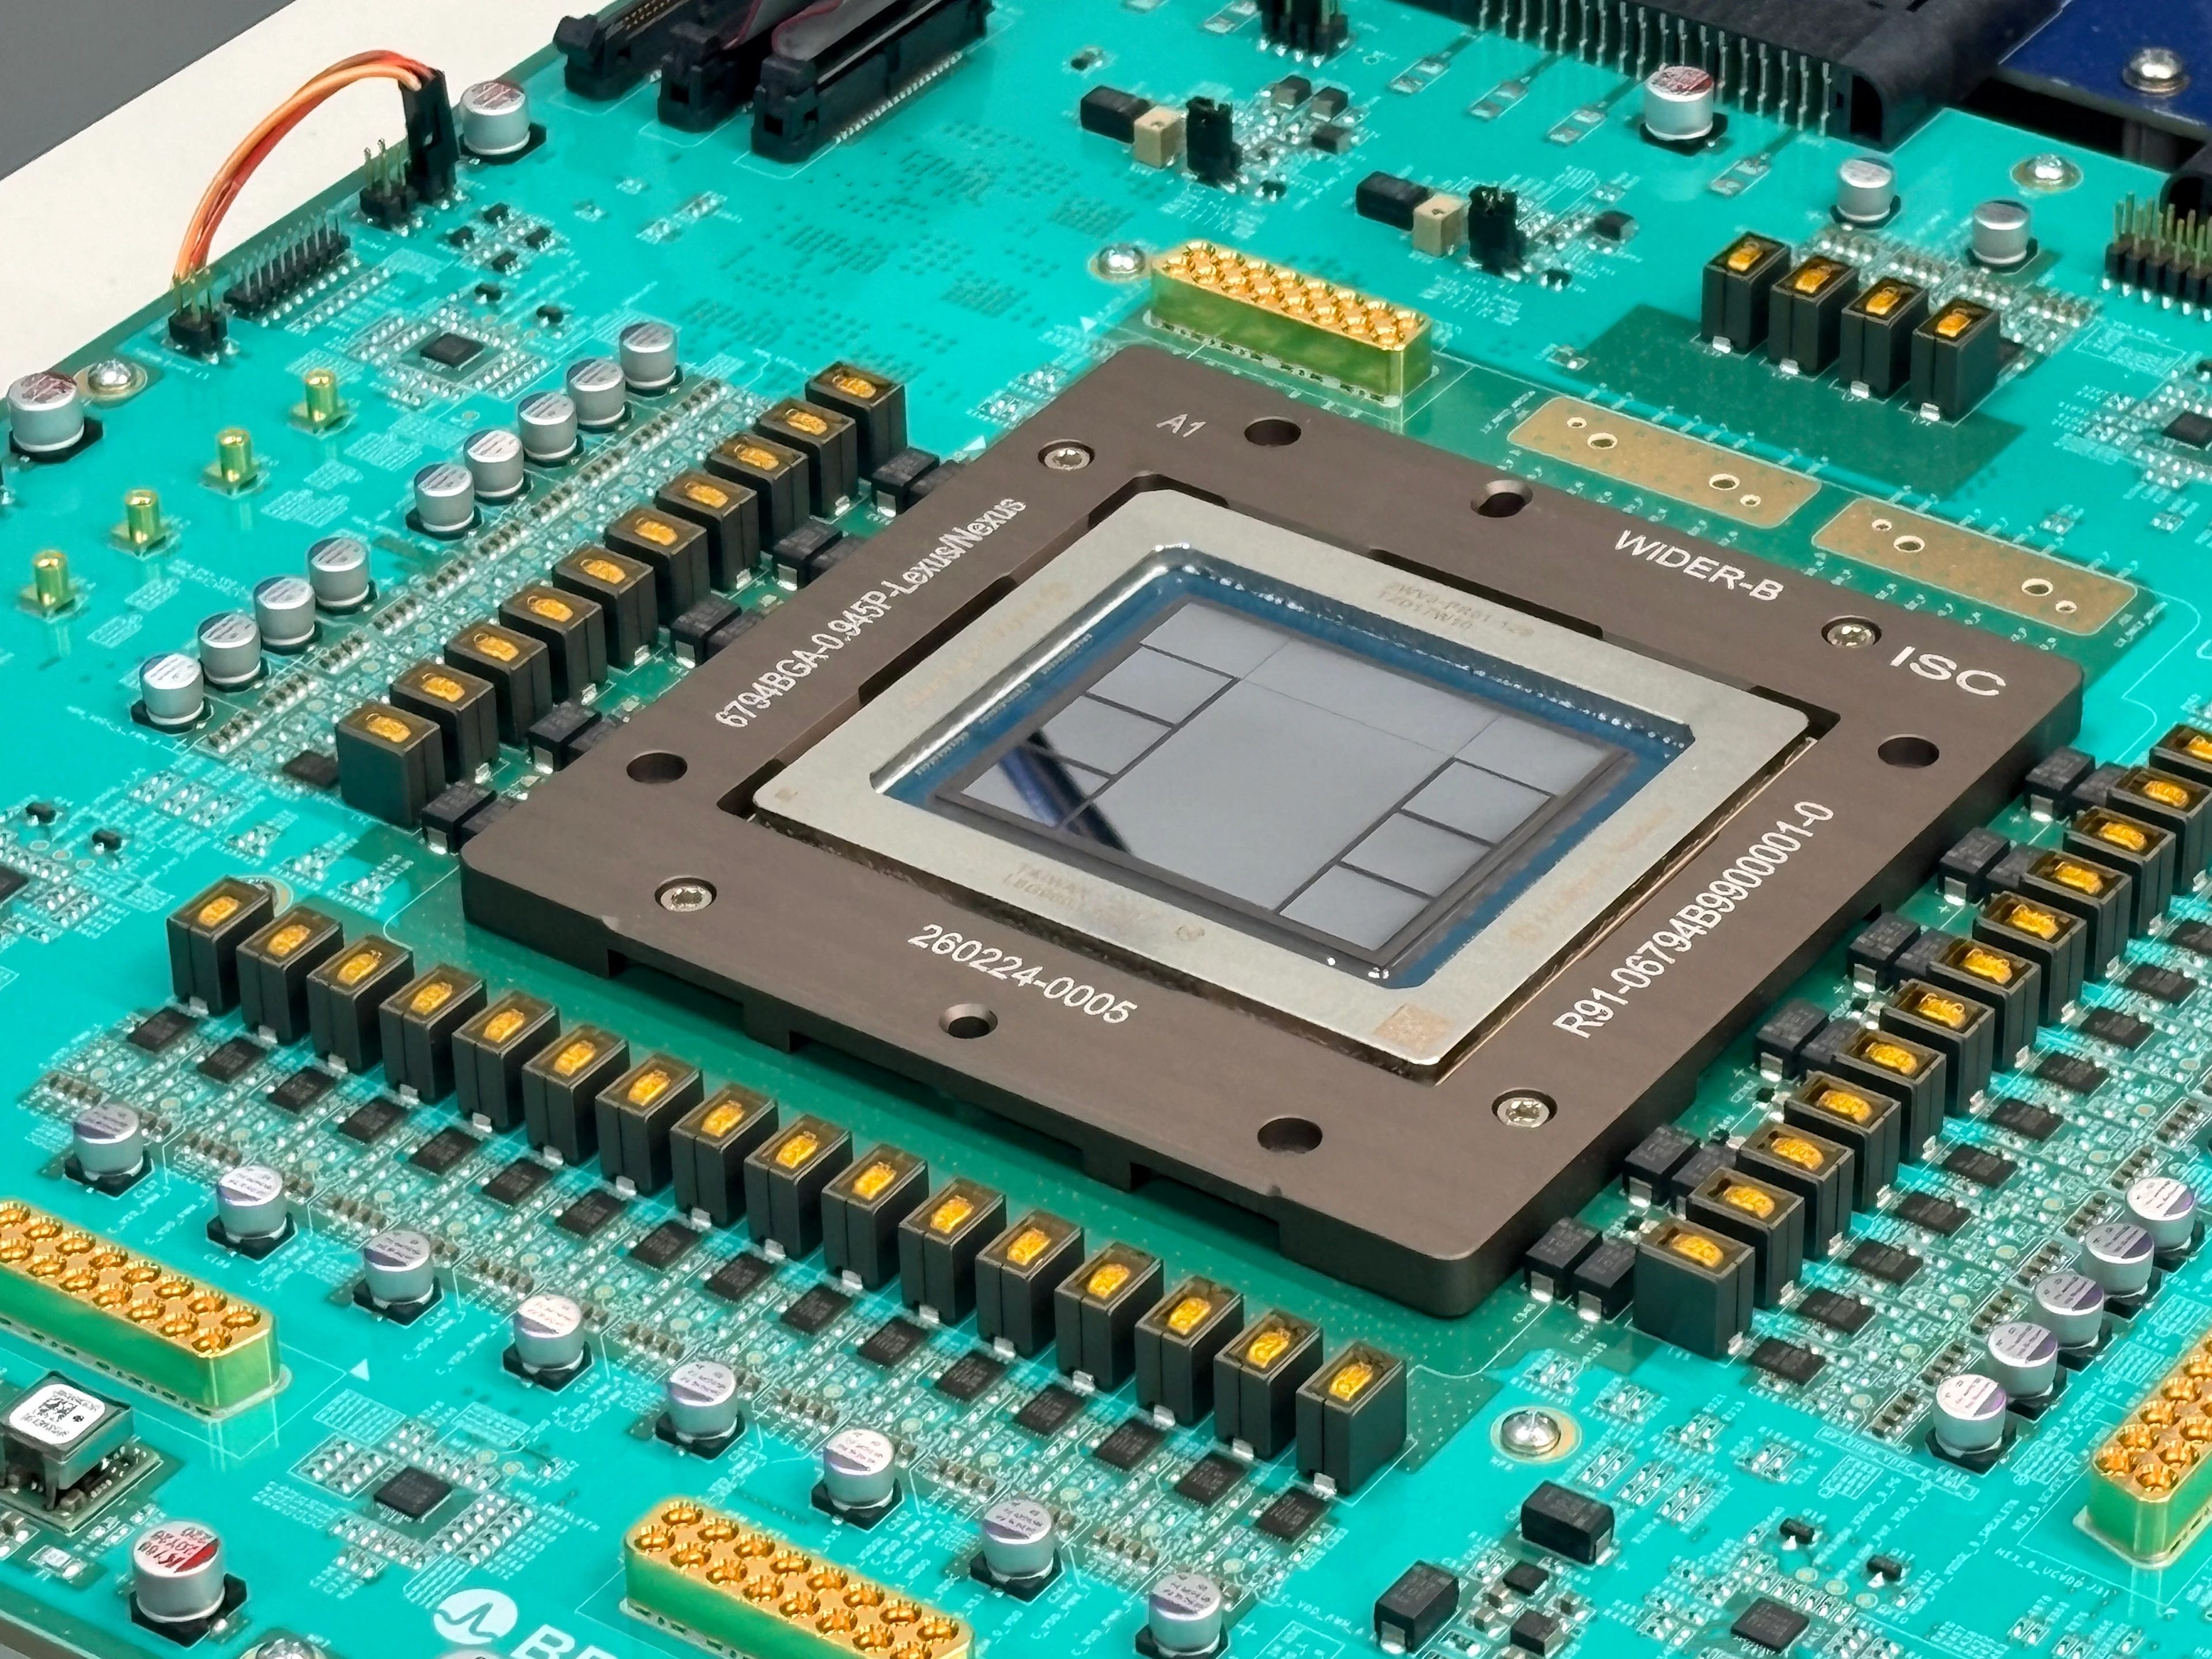
The largest buyer of AI compute in the world now designs its own inference silicon. We separate what OpenAI and Broadcom actually confirmed from the noise, and ask the five questions that matter: is it legit, can they scale it, what it means for Nvidia, what it means for Cerebras, and whether the market is still enormous enough for everyone to win at once.
On June 24, 2026, OpenAI and Broadcom stood on a stage and handed Sam Altman a piece of silicon named after a pepper. This week, at Hot Chips 2026, the same team came back with benchmarks. The headline that ran everywhere was that a first-generation, in-house inference chip had, on a public test suite, out-run Nvidia’s flagship rack systems on tokens per watt. That is a genuinely arresting claim, and most of the coverage has spent its energy litigating it. We think that is the wrong fight. The interesting question about Jalapeno was never whether OpenAI could design a competitive chip. A company with OpenAI’s cash, its recruiting pull, and Broadcom and TSMC standing behind it was always going to tape out something respectable. The interesting questions are the ones that determine whether this matters to a portfolio: can it be built in volume, what does it do to Nvidia’s economics, what it means for the newly public inference specialists, and whether the pie is still large enough that all of this can be true at once without anyone important losing.
This piece is LongYield’s own attempt to answer those questions. We have tried to be disciplined about a distinction the market keeps blurring: the difference between what OpenAI and its partners have actually confirmed, what credible trade press has reported, and what is still analysis or outright speculation. We label those categories throughout, and we close with a two-column ledger that keeps the hard facts and the opinions physically separate. Where the specifics differ from the popular framing, we go with the primary sources. The name really is Jalapeno, for the record. It is not a leaked internal codename that got out ahead of a sanitized product name; it is what OpenAI itself calls the chip in its own announcement, part of a run of deliberately silly kitchen names (the host tray is “Katsu,” the accelerator tray “Vindaloo,” the switch tray “Chana,” the serving engine “Teacup”) that tells you something about the culture of the team that built it.
The question about Jalapeno was never whether OpenAI could design a good chip. It was whether the world’s largest compute buyer can manufacture, power, and operate one at the only scale that would move its own bill, let alone anyone else’s.
LongYield · The Compute Desk
01 · The Fact Base
What OpenAI actually announced, in order
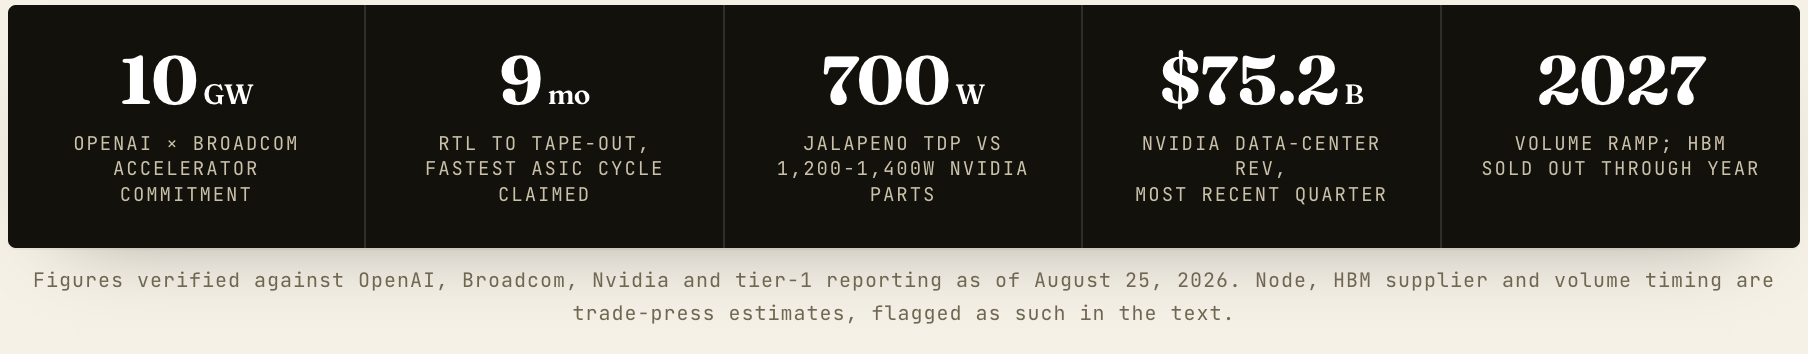
Three distinct events sit behind the “OpenAI chip” story, and conflating them is the first way to get this wrong. The commercial frame came first. On October 13, 2025, OpenAI and Broadcom announced a strategic collaboration to deploy 10 gigawatts of OpenAI-designed AI accelerators, with Broadcom building the racks and networking, deployments starting in the second half of 2026 and completing by the end of 2029. That is the number that matters for scale, and we return to it repeatedly below. Ten gigawatts is not a chip; it is a multi-year build-out roughly on the order of the entire installed base of a large cloud region, and the two companies were explicit that it would land across both OpenAI facilities and partner data centers, wired end to end with Broadcom Ethernet.
The product came second. On June 24, 2026, the companies unveiled the chip itself, Jalapeno, described by OpenAI as its first “Intelligence Processor” and, crucially, as an accelerator built from a blank slate for large-language-model inference, not training. OpenAI designed the architecture; Broadcom handles silicon implementation and networking (including its Tomahawk switching silicon); and Celestica does board, rack and system integration. Note who is not on that list: the popular framing that this is a Broadcom-and-Marvell effort is not what OpenAI confirmed. Marvell does custom silicon for other hyperscalers, but the named partners here are Broadcom and Celestica.
The evidence came third, and it came this week. At Hot Chips 2026, OpenAI presented architectural detail and performance data, and SemiAnalysis published a hands-on account after running its InferenceX benchmark suite alongside OpenAI engineers in the company’s own lab. This is the material that turned Jalapeno from a press-release chip into something the market has to take seriously, because independent analysts put hands on it. It is also where the load-bearing caveats live.
The confirmed technical picture
Stripping out the adjectives, here is what has actually been shown. Jalapeno is a reticle-sized compute die paired with six stacks of HBM4, totaling 216 GiB at 15.4 TB/s of package bandwidth. The part carries a 700W TDP (measured sustained power reportedly stayed at or below 550W in testing) against Nvidia GB200 and GB300 accelerators rated at 1,200W and 1,400W. The current benchmarked silicon is the “A0” stepping; a “B0” revision already in the fab is reported to deliver roughly 25% better performance per watt, with about 13.4 petaFLOPS of MXFP4 on a single die built on TSMC’s N3P process, with an N3E I/O chiplet alongside. That node detail comes from SemiAnalysis and Tom’s Hardware, not from OpenAI’s own release, so we treat it as well-sourced reporting rather than a company-confirmed spec.
On performance, the reported figures are 1.5x to 1.9x more throughput per kilowatt and 1.7x to 3.6x lower end-to-end latency than GB200 and GB300 rack systems on the InferenceX suite, widening to enormous multiples (8x and up) at the lowest-latency operating points. Those numbers are real in the sense that a credible third party watched them run on three open models: GPT-OSS 120B, DeepSeek R1 (670B), and Moonshot’s trillion-parameter Kimi K2.5. They are also narrow: the tests are single-turn 8k-input, 1k-output shapes, the easiest workload to tune for; the comparison normalizes to each chip’s rated package TDP; Jalapeno ran without speculative decoding while some Nvidia configurations did not; and, most importantly, Jalapeno was not benchmarked against Vera Rubin, Nvidia’s HBM4-generation part that is the true like-for-like comparison and is already shipping to customers. Against Rubin’s published July numbers, SemiAnalysis puts the two roughly head to head on cost per token, with Jalapeno holding an efficiency edge that shrinks considerably once you account for the software levers Nvidia has and OpenAI has not yet pulled.
The single most important sentence in the coverage
OpenAI taped out Jalapeno (specifically, the full CoWoS package design, not just the top die) in November 2025. It has engineering samples running today. But production is reported to ramp gradually across 2027, with most output scheduled for the fourth quarter of next year. The chip that beat the benchmarks and the chip that shows up in data centers at scale are separated by more than a year of manufacturing, yield learning, and supply allocation. Every judgment below flows from that gap.
Two more confirmed points frame everything. First, the development speed is not a rounding error in the story; it is central to it. OpenAI says the nine-month RTL-to-tape-out cycle is the fastest ever for a high-performance advanced-node ASIC, and that it used its own models to accelerate the design, citing an 8% reduction in SIMD area and a 10% reduction in matrix-engine area from AI-assisted work. The chip team, led by hardware VP Richard Ho (a Google TPU alumnus), began serious hiring in mid-2024, which puts the true team-to-tape-out clock closer to sixteen months. Second, OpenAI has been emphatic that Jalapeno does not change its Nvidia relationship in the near term. On August 17, Nvidia agreed to provide up to $105 billion of financing tied to an OpenAI-leased data-center campus in Ohio, and Ho told Bloomberg the same week, in plain language, “Nvidia is a really good partner, and we continue to need a lot of Nvidia.” Both things are true at once, and the market’s job is to hold them together.
02 · Question One
Is it legit? Yes, and that was the easy part
Our verdict on credibility is clear: this is a real, serious silicon program, not vaporware. Three things carry that judgment, and none of them depends on taking OpenAI’s own benchmark slides at face value.
The first is the caliber of the partners. Broadcom is not a hopeful startup; it is the most proven custom-ASIC house in the industry, the company that co-designed Google’s TPU program and builds custom accelerators for multiple hyperscalers. TSMC, whether or not OpenAI names it, is the only foundry that manufactures leading-edge AI silicon at scale, and a 3nm-class part packaged in CoWoS is exactly what it produces for everyone else. Celestica is a tier-one systems integrator. When a company with this much capital hires a TPU-pedigree leader and pairs him with that supply chain, the base rate on “does a competitive chip come out the other end” is high. The precedent is not speculative. Google’s TPU is now in its seventh generation (Ironwood), Amazon’s Trainium is on its third and reportedly powers workloads for both Anthropic and OpenAI, Meta is shipping MTIA with a roadmap of four further generations disclosed, and Microsoft has Maia in the field. Custom hyperscaler silicon that works is a solved problem in the sense that it has been done, repeatedly, by less software-capable organizations than OpenAI.
The second is that an independent analyst put hands on the part. SemiAnalysis ran its own InferenceX suite on Jalapeno in OpenAI’s lab and came away describing it as beating “every Nvidia, AMD, and Google chip we have been able to test” on the models available. We would discount a vendor’s self-published numbers heavily; we discount a third party’s supervised lab run much less. The models were real and open, the evals (GSM8k parity with Nvidia chips) checked out, and, in a detail that is half a joke and half a genuine signal of a working software stack, the team ported Doom to the chip with nothing but Codex prompts and ran it at 36 frames per second.
The third, and to us the most persuasive, is the software story, because software is where first-generation accelerators usually die. The graveyard of AI silicon is full of chips with fine hardware and no compiler. Jalapeno’s early results were achieved on a from-scratch stack, using OpenAI’s own kernel language (Gluon, built on Triton) and, tellingly, using an internal, scaled-up version of Codex to write and tune kernels that would normally consume a large human engineering team for a year. OpenAI did not even have an implementation of the MLA attention kernel until it benchmarked DeepSeek; Codex wrote functional, efficient kernels fast enough that the human kernel team reportedly did not need to intervene. That is the part that should make a competitor nervous, because it is the part that does not generalize to rivals who lack a frontier model to point at their own toolchain.
OpenAI used the model you can rent today to write the kernels for the chip that may run tomorrow’s model. Nvidia’s own GPUs are helping bring up their potential successor in real time.
On the software flywheel behind Jalapeno
So where is the skepticism warranted? Not on whether the chip exists or works, but on the framing around it. The benchmarks are early-silicon, single-turn, favorable-shape results that have not been run on the long-context, multi-turn, agentic workloads that stress real production serving (SemiAnalysis is explicit that its harder AgentX suite has not been run on Jalapeno). The comparison of choice was GB300, not the HBM4-generation Rubin that is the honest peer. And a first-generation part carries first-generation risks that no amount of design talent erases: the B0 stepping exists precisely because A0 needed fixing, yields on a reticle-limit die are unproven at volume, and the entire program has roughly three months of real silicon bring-up behind it. Legit, yes. Finished, no. The distance between those two words is the rest of this report.
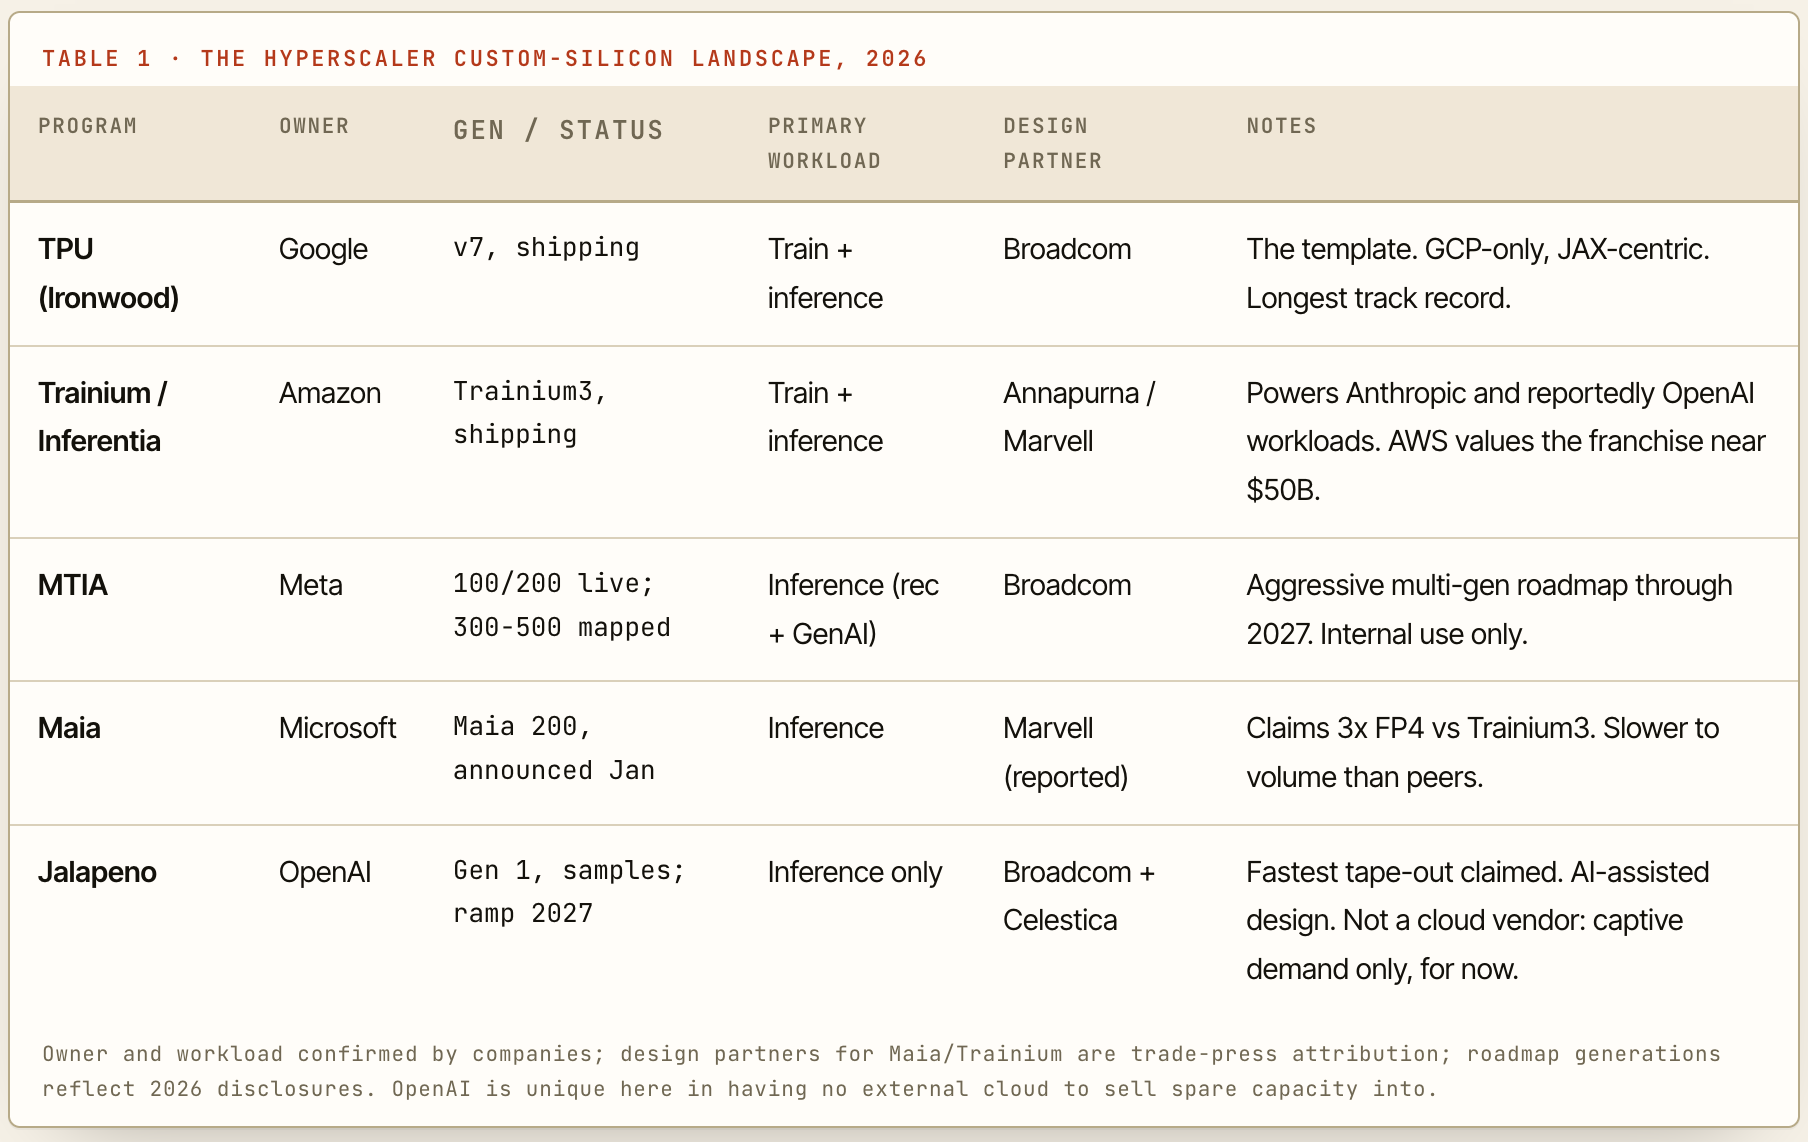
That last column is the quiet strategic tell. Every other program on the list belongs to a cloud provider that can monetize idle silicon by renting it. OpenAI has no cloud. Every Jalapeno it builds has to be fed by OpenAI’s own inference demand, which is enormous but also the only demand it has. That makes the scaling question, not the credibility question, the one that decides whether this program bends the industry or merely trims OpenAI’s own cost of goods.
03 · Question Two
